What Is DevOps and How Does It Work?

Mayank Patel
Feb 23, 2022
5 min read
Last updated Jun 26, 2024
Do you know the challenges a software development company had faced before the foundation of DevOps? We are a prominent cloud service provider in India & USA and hence quite aware of everything.
Also, being a reliable DevOps company in India, we always encourage people to go with the evolving technologies. Hire the best DevOps developers in India exclusively from the panel of our experts.
The biggest challenge was code deployment. You must be thinking, why and how? Once the developer completes the code, he deploys it on the server by being in the coordination of the operations team.
Now, the code created problems during deployment, and a fight between both departments started. The developer said, the problem is because of the server, and the operations team said, the code had created the problem. And the ball is kept roaming from one court to another.
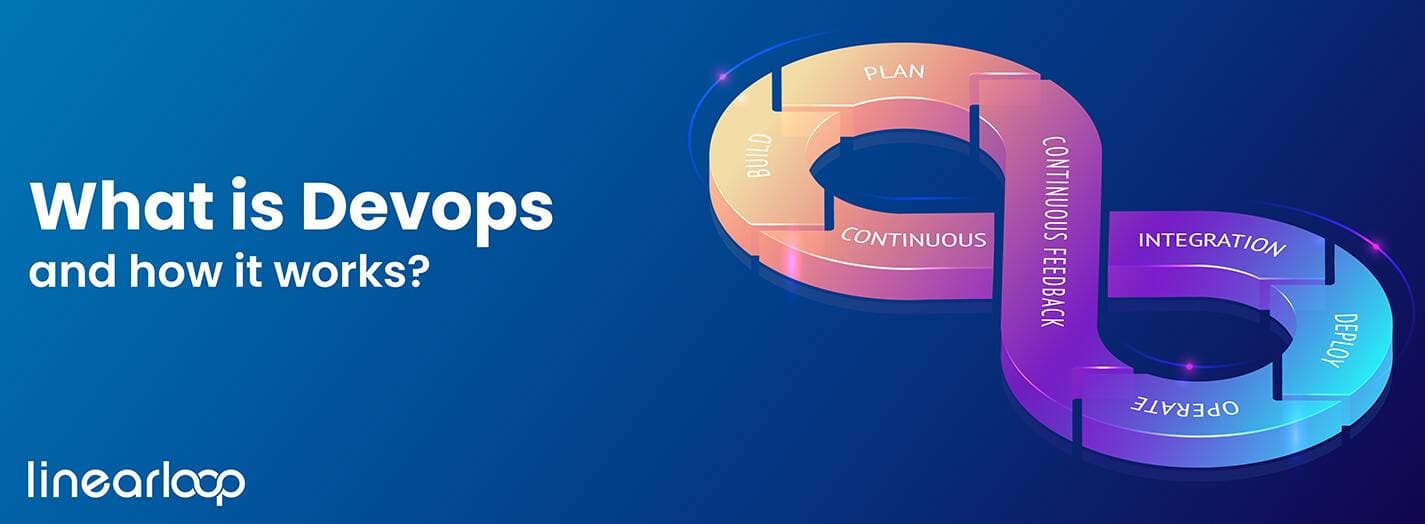
DevOps (Development + Operations) came into existence to rectify this challenge. The main role of DevOps technologies is to maintain coordination between the development and operations teams.
It facilitates an environment where both of them can work in synchronization and no confusion or blame game will take place.
We can define DevOps as a united process where Teams, Processes, and Products will work in synch. Further, it follows CI & CD (Continuous Integration & Continuous Delivery) that adds value to the product.
Apart from that, DevOps accelerates the pace of product delivery as a result of which clients get more time for marketing and building strategies.
DevOps reduces the potential risks because the evolution of Continuous Delivery enables stakeholders to share their feedback at an early stage.
Furthermore, DevOps facilitates common methodologies that include microservices, containers, and cloud computing. However, Linearloop is one of the renowned cloud computing companies.
If you need any support regarding cloud computing services, feel free to get in touch.
As we have mentioned above, bringing two business units (Development and Operations) in coordination is the primary job of DevOps Technologies.
The operations and development team work together during the entire software development process. It starts with design to development to production and finishes with support.
Following the best practices, the ultimate intent of each team and participating member is to achieve the desired goal.
Further, all the stakeholders, clients, and other parties will be in the loop because of continuous integration and continuous delivery.
Both the concepts give them the flexibility to share required feedback as early as possible. As a result, development costs and time, both are saved.
IT industries are aggressively shifting their focus towards DevOps technologies because it has a result-driven approach. Apart from that, DevOps is one of the most demanding technologies because of its versatile features.
Let’s have a look at the benefits of DevOps.
Smooth Coordination: The biggest benefit of DevOps, is well-coordinated communication between the development and operation team. It offers an independent environment to the teams by being in coordination.
Speed: DevOps ensures fast delivery because of Continuous Integration and Continuous Delivery and it is also based on Agile principles.
Increased Reliability: As we know, DevOps follows the best practices for Continuous Integration, Continuous Deployment, and Automation Testing. As a result, we get reliable and robust business application.
Security: DevOps ensures the security of a product by following process automation and compliance policies. Further, if an application is developed using DevOps technologies, its security will never be compromised.
Management of Risk: Another most important benefit of DevOps is the management of risks. It allows early detection of bugs that may create a big problem at the coming stages. Early bug detection saves time as well as cost.
DevOps Tools
Knowledge of leading DevOps tools is a must. We know programming is all about mindset, but if you have enough information about the tools, your performance will be more impactful.
Code Repositories: Code repositories allow multiple developers to work on the code. Additionally, it gives flexibility to the developers to code in & out, and they will also be able to go back to the older versions.
The tool also keeps the record of modifications made in the code. Developers will be required to monitor the changes so that they can update themselves with the recent change.
Artifact Repositories: Artifact contains the compiled source code for testing. Further, it enables object-based and version-controlled output. Both these approaches made the concept more significant and best practice.
CI/CD Pipeline Engines: The software development process becomes more prominent because of CI/CD. It allows frequent validation and delivery of the application.
Following the approach of continuous integration (CI), developers can build test, and validate the code using a shared repository. No manual intervention is required.
With continuous delivery (CD), quick execution & configuration set up for the release can be achieved. And with continuous deployment, it goes one step ahead. It involves testing, configuration, monitoring, analysis, and provisioning.
Some familiar CI/CD tools are Jenkins, TeamCity, Circle CI, Bamboo, Gitlab, Buddy, Travis CI.
Containers: With the help of Containers, multiple developers get individual infrastructure for development, testing, production, support, etc.
One of the popular containerization software is Docker. However, Microsoft offers multiple options for windows containers. Linearloop has a strong command over Docker development services, and you can hire docker developers for your projects.
Cloud Environments: To execute automated deployment, DevOps follow cloud infrastructure. The most commonly used cloud providers are AWS & Microsoft Azure. Further, Linearloop is also your constant partner for the services.
Also, hire AWS experts in India & USA from here as we have great and experienced people in our team.
As far as, our cloud computing services are concerned, we came in top cloud computing companies in India.
Explore the key challenges that DevOps often face and we also explained how they overcome those challenges.
1. Cultural Resistance: One of the most common challenges in adopting DevOps is cultural resistance. You will see that traditional organizational structures often create silos where development, operations, and other departments work in isolation. Due to this separation “us vs them” culture starts and it can be very harmful for a company. You can overcome this cultural resistance by applying the points mentioned below.
- Communication and Training: Regularly communicate the benefits of DevOps and provide training to help team members understand its value.
- Cross-Functional Teams: You should create cross-functional teams that include members from development, operations, and other relevant departments. This integration helps build trust and encourages collaboration.
- Recognition and Rewards: Recognize and reward the collaborative behavior and achievements that perfectly match the principles of DevOps.
2. Legacy Systems Integration: Nowadays many companies have legacy systems that are not designed to work with the latest DevOps tools and practices. Integration of these systems can be complex and time-consuming as it can delay the adoption of DevOps. To overcome this challenge organizations should apply these points:
- Assessment and Planning: You should conduct a thorough assessment of existing systems to understand the integration requirements and potential obstacles. Develop a detailed integration plan that includes phased implementation to minimize delays.
- Incremental Approach: Implement the modern DevOps practices incrementally and start with the areas that are easier to modernize. This approach allows for slow integration of legacy systems while showing early successes.
- Modernization and Refactoring: Easily modernize and refactor legacy applications to make them more compatible with DevOps standards. This might include breaking monolithic applications into microservices or adopting APIs for better integration.
3. Security Concerns: Integrating security into the DevOps pipeline is often known as DevSecOps and it can be challenging. Traditional security standards may not match with the fast-paced and iterative nature of DevOps which can lead to vulnerabilities. Overcome this challenge by integrating these security points given below:
- Shift Left Security: Integrate security standards early in the development process (shifting left) to identify and address vulnerabilities before they reach production.
- Automation of Security Testing: Use different types of automated security testing tools to continuously scan code and applications for vulnerabilities. Integrate these tools into the CI/CD pipeline to ensure that security checks are part of the development workflow.
- Security Training: You should provide training about secure coding practices and emerging security threats to your developers and operations teams. This knowledge allows the teams to build security into their processes.
4. Managing Complex Environments: DevOps environments can become highly complex, especially in large organizations with different types of applications and infrastructure. Managing this complexity while maintaining consistency and control is considered a big challenge. You can overcome this challenge by following these points.
- Infrastructure as Code (IaC): Include the Infrastructure as Code (IaC) to manage and provision environments consistently. Different types of tools like Terraform, Ansible, and Kubernetes can help automate the configuration and scaling of complex environments.
- Monitoring and Logging: Implement thorough monitoring and logging to gain visibility into your systems and quickly identify issues.
- Configuration Management: Start using configuration management tools because it ensures that all environments are consistent and reproducible while reducing the risk of configuration drift.
Explore this section to determine the future of DevOps.
1. Emerging Trends and Technologies:
- GitOps: GitOps is an approach that uses Git repositories as the single source to manage infrastructure and application configurations. This trend indicates declarative configurations and automating updates through Git workflows.
- DevSecOps: Integrating the latest security standards into the DevOps process is known as DevSecOps and it ensures that security is a shared responsibility from the start. This trend is getting popular as organizations are prioritizing security in their software development lifecycle.
- AI and Machine Learning in DevOps: The use of AI and ML helps optimize DevOps processes like predictive analytics to identify potential issues before they occur through automated code reviews and intelligent incident management.
- Serverless Computing: Serverless architecture allows the developers to build and run different types of applications without managing infrastructure. This trend is affecting how applications are deployed and scaled in a DevOps environment.
2. Predictions for the Evolution of DevOps Processes:
- Greater focus on Collaborative Tools: As remote and hybrid work models become more usual the usage of various tools ensures flawless collaboration so that it can become an integral part of DevOps practices.
- Expansion of DevOps: The principles of DevOps will continue to be adopted in other areas of organizations like HR, finance, and marketing which promotes the culture of continuous improvement and agility.
- Evolution of DevOps: As DevOps grows, the metrics used to measure its success will evolve and it includes more detailed indicators of performance like business value metrics and customer satisfaction scores.
Conclusion
DevOps is one of the evolving technologies, and it has strengthened the software development process. Further, with the implementation of DevOps, the applications become more reliable, robust, focused, and result-driven.
Utilizing our practical experience, we have mentioned best practices for DevOps with its features.
At Linearloop, we aim to work with the leading technologies, and DevOps is one of them. We have delivered countless projects in DevOps across the globe.
Added, we offer end-to-end support for DevOps and Cloud Computing Services. We are a leading cloud service provider in India & USA and if you have any doubt, feel free to connect.
We hope now you have an idea about DevOps and how DevOps work? Also, we will be looking into your queries.
Related Posts

Why DevOps Mental Models Fail for MLOps in Production AI
Most teams break AI systems by doing something familiar. They take the same DevOps playbook that made their software reliable, scalable, and fast to ship and apply it to models in production. Pipelines turn green, deployments succeed, dashboards stay quiet, and yet, the system starts making worse decisions.
The problem isn’t tooling or effort. It’s a category error. DevOps is built for deterministic systems where correctness is stable once code ships. AI systems don’t behave that way. Their behaviour shifts with data, time, and feedback. This is why teams keep getting blindsided in production. They monitor infrastructure health while model behaviour quietly degrades. They roll back code while the data has already moved on. Treating MLOps like DevOps systematically hides the failures that matter most.
DevOps works because software systems behave in ways engineers can reason about, predict, and control. The mental models behind DevOps were shaped by years of operating deterministic code at scale. When something breaks, there is usually a clear cause, a reproducible failure, and a reliable way to restore a known-good state. That alignment between how software behaves and how DevOps operates is why the model holds so well in production.
- Code is deterministic; the same input produces the same output until the code changes.
- Failures are binary; the service is either working or it isn’t.
- Tests approximate production behaviour closely enough to catch most regressions.
- Deployments change logic.
- Rollbacks reliably return the system to a previous, correct state.
- Monitoring focuses on availability, latency, errors, and saturation.
- System health is largely infrastructure health.
- State is explicit and versioned.
- User behaviour does not directly rewrite the system’s logic.
- Time does not silently change correctness once code is live.
The moment a model enters production, you stop operating software and start operating behaviour. The system is no longer deterministic, and correctness is no longer stable. Even if the code never changes, outcomes do.
Models are probabilistic by design. Identical inputs do not guarantee identical outputs over time because behaviour is learned from data, not encoded in logic. That behaviour is tightly coupled to training data, feature pipelines, and the live input distribution. When the distribution shifts, as it always does in production, model correctness shifts with it. Nothing fails loudly. The system keeps responding and it becomes wrong.
Production data introduces a state that DevOps systems rarely face. User behaviour influences future inputs. Model outputs change user decisions. Those decisions feed back into training data. Small errors compound through feedback loops, slowly rewriting the conditions under which the model was valid.
Time becomes an active failure vector. Correctness decays even without deployments. Rollbacks don’t restore reality. Tests can’t represent live conditions because labels are delayed or incomplete. Infrastructure metrics stay green while decision quality degrades underneath. This is the fundamental change: Models turn production systems into evolving, self-influencing systems that DevOps mental models are not built to control.
Also Read: Canary Releases in Serverless: DevOps Best Practices for Safer Deployments
Once models are live, most teams don’t rethink how they operate systems. They inherit DevOps assumptions by default, because those assumptions have been correct for years. The problem is that these assumptions no longer map to how ML systems behave in production. Each one creates a blind spot that compounds over time.
In DevOps, a green pipeline usually signals safety. The code is tested, deployed, and running as expected. In MLOps, a successful deploy only confirms that the model binary is live. It says nothing about whether predictions are correct, calibrated, or still aligned with reality. Behaviour can be wrong from the first request, and nothing in the deployment process will tell you.
Teams rely on offline metrics, validation datasets, and pre-deploy checks to assert readiness. This works for software because production behaviour is stable. ML systems face delayed labels, partial feedback, and shifting data distributions. Tests validate performance on past data, while production failures emerge from data the system has never seen.
Latency, error rates, and uptime remain the primary health signals. These metrics stay green even when prediction quality collapses. Models can degrade silently, serving confident but wrong outputs, without triggering a single infrastructure alert. The system appears healthy while decision quality erodes underneath.
DevOps assumes you can return to a known-good state. ML systems don’t have one. Rolling back a model doesn’t roll back user behaviour, incoming data, or feedback loops already influenced by previous outputs. By the time a rollback happens, the environment the old model was trained for no longer exists.
In production, these assumptions fail in ways that standard DevOps signals are structurally unable to detect. The system keeps responding, pipelines stay green, and incident dashboards remain calm, while decision quality degrades underneath. By the time teams notice, the damage is already systemic rather than isolated.
- Silent Quality Degradation: Models rarely fail in a single step. Accuracy, calibration, or relevance decays gradually as live data drifts away from training distributions. Because no request errors out, nothing triggers an alert. The system looks healthy, but each decision is slightly worse than the last, compounding into measurable business impact.
- Feedback Loops that Amplify Small Errors: Model outputs influence user behaviour, which reshapes future inputs. Small prediction errors change actions, those actions alter data, and the next training cycle reinforces the drift. What starts as minor misalignment becomes a self-amplifying loop that pushes the system further from correctness with every iteration.
- Business Impact Before Systems Alert: By the time teams see infrastructure anomalies, users have already adapted or lost trust. Conversion drops, recommendations feel off, risk signals misfire. The system didn’t crash, so no one reacted early. The failure shows up first in business metrics, long before any DevOps alarm sounds.
Also Read: How to Use Shadow Traffic to Validate Real-World Reliability
Adding more MLOps tooling feels like progress because it looks like control. More dashboards, more pipelines, more automation. But tools don’t correct mental models. They inherit them.
Most MLOps stacks are built as extensions of DevOps: CI pipelines for models, registries for artifacts, deployment automation, and infra monitoring. These solve delivery problems, not behavioural ones. They make it easier to ship models, not to understand whether those models are still correct in a changing environment.
When the underlying assumption is “if it deploys cleanly, it’s safe,” tools reinforce false confidence. Drift detectors fire after damage is done. Offline evaluations lag reality. Alerts remain tied to infrastructure health rather than decision quality. The system becomes better instrumented, but no more observable where it matters.
This is why teams with mature MLOps stacks still get blindsided in production. They didn’t lack tooling. They lacked a model of operations that treats behaviour, data, and time as first-class production concerns. Without that shift, more tools simply help teams fail faster and more quietly.
Also Read: How to Manage Kubernetes CRDs Across Teams Using DevOps Best Practices
DevOps optimises for safe delivery. MLOps must optimise for sustained correctness. The difference matters because model behaviour changes even when code doesn’t. Fixing production AI requires adding capabilities DevOps was never built to handle but new control surfaces.
- Behaviour as a first-class production signal: In software, correctness is assumed once deployed. In ML, behaviour is the system. Prediction quality, calibration, confidence, and outcome alignment must be observed continuously.
- Data as a production dependency: Data is not just input. It defines system behaviour. Training data, features, and live distributions must be observable, versioned, and owned. When data shifts, the system changes without a deploy.
- Time-aware operations: ML systems decay by default. Environments change, users adapt, and feedback loops compound. Correctness erodes even when nothing ships. MLOps must assume models have a shelf life and design operations around continuous validation, decay detection, and retraining triggers.
If your AI keeps breaking in production, the instinct is usually to stabilise deployments or add more checks. That rarely helps. The failures you’re seeing are caused by what you’re not observing once they’re live. The fastest way to regain control is to fix the operating model, not the tooling.
- Stop equating deployment success with system health: Treat model deployment as the start of validation, not the end. A live model without behavioural monitoring is an unverified system, no matter how clean the release was.
- Make behavioural metrics non-negotiable: Track prediction quality, confidence, calibration, and outcome alignment continuously. If you can’t tell whether decisions are getting worse, you’re already operating blind.
- Surface data drift before it becomes a model problem: Monitor input distributions and feature integrity explicitly. Drift is a production risk that needs early visibility.
- Assign end-to-end ownership for model behaviour: One team must own outcomes across data, model, and production. Fragmented ownership guarantees delayed detection and slow response.
- Design for decay: Assume every model will degrade. Build retraining triggers, validation loops, and expiry assumptions into operations from day one.
AI systems break in production because teams operate them using mental models built for software. DevOps gives you speed, repeatability, and safety at the point of delivery. It does not guarantee correctness once a model is exposed to real data, real users, and time.
MLOps isn’t a broken version of DevOps. It’s a different operational problem. One that requires treating behaviour, data, and decay as first-class production concerns. Until teams make that shift, pipelines will stay green while systems quietly drift away from correctness.
At Linearloop, this is exactly the gap we help teams close. We work with engineering leaders to redesign how AI systems are operated in production, focusing on behavioural observability, ownership, and long-term reliability, not just deployment mechanics. If your AI looks healthy but keeps making the wrong decisions, it’s an operating model problem, and that’s where we come in.

Mayank Patel
Jan 28, 20266 min read

Canary Releases in Serverless: DevOps Best Practices for Safer Deployments
Serverless makes deployments feel deceptively simple: you push code, the platform scales it automatically, and production traffic begins flowing almost immediately. But that same speed can turn small mistakes into large incidents when something goes wrong. In a serverless environment, a faulty release rarely fails in isolation because the platform fans it out across thousands of concurrent executions before you have enough signals to react, which means the cost, reliability, and user impact escalate faster than most teams expect.
This is where canary releases stop being an optional optimisation and become a core part of DevOps best practices, especially if you care about maintaining deployment velocity without gambling on production stability. Without a controlled canary, every serverless deployment is effectively a full cutover, where rollback happens only after real damage has already occurred.
If you already run serverless workloads in production and want to ship changes safely without adding process overhead or slowing teams down, this blog is for you. The focus here is on the operational practices that help you detect failures early, contain blast radius, and automate rollback before a bad release turns into a widespread outage.
Serverless removes servers, but it doesn’t remove failure. It changes how failure spreads.
In traditional systems, a bad deploy usually rolls out gradually. But in serverless, none of that friction exists. The platform scales your mistake instantly. If your function is triggered by traffic, events, or retries, a faulty release can fan out across thousands of executions in seconds.
While auto-scaling is the first multiplier, retries are the second. Many serverless workloads are event-driven. When something fails, the platform retries automatically. That can mask the original failure while increasing load, cost, and downstream pressure. You think you have resilience. What you actually have is amplified failure.
Observability is the third problem. Functions are short-lived, logs are fragmented, and errors may not surface where you expect them. By the time dashboards catch up, the damage is already done.
This is why applying traditional deployment thinking to serverless breaks down. The system behaves differently under failure. Canary releases aren’t about polish here. They’re a safety mechanism that compensates for the speed, scale, and automation that serverless introduces.
Also Read: How to Use Shadow Traffic to Validate Real-World Reliability
In serverless systems, deployment safety is not optional. The platform removes friction, but that friction was often the only thing slowing failures down. When every release can scale instantly, you need a way to validate changes under real production conditions without exposing the entire system to risk.
That’s where canary releases fit into DevOps best practices. They turn deployments from a single irreversible action into a controlled experiment.
- They limit blast radius by default: Canary releases ensure that a bad change only affects a small slice of traffic or events. Instead of failing everywhere at once, failures stay contained and reversible.
- They shift validation from theory to production reality: Pre-prod tests don’t capture real traffic patterns, retries, or edge cases. Canaries let you validate changes against live behaviour without full exposure.
- They enable fast, automated rollback: When rollback is built into the release flow, recovery doesn’t depend on human reaction time. The system corrects itself before incidents escalate.
Once you accept canary releases as a baseline DevOps best practice, the next question is how to do them safely. In serverless systems, safety comes from designing deployments that assume failure and limit its impact by default.
The principles below are what separate controlled rollouts from accidental production experiments:
- Contain the blast radius first, optimise later: Always limit how much traffic or how many events a new version can touch before worrying about rollout speed.
- Observe before you trust: If you can’t see errors, latency shifts, retries, and cost changes in near real time, your canary isn’t doing its job.
- Automate rollback: Rollback must trigger on signals, not opinions. Humans are always slower than failing systems.
- Time-box every canary: A canary that runs indefinitely stops being a safety mechanism and becomes technical debt.
- Assume retries will lie to you: Retries can hide failures while amplifying load. Design your signals to catch this early.
- Prefer boring over clever: Simple, predictable rollout rules beat complex logic when things start breaking.
Also Read: How to Manage Kubernetes CRDs Across Teams Using DevOps Best Practices
Once the principles are clear, execution comes down to routing. In serverless systems, routing is where most canary strategies either work cleanly or fall apart. You’re not just shifting user traffic. You’re controlling how requests, events, and retries reach different function versions under real load. So, the strategy you choose has to reflect how your system is triggered.
Request-driven workloads are the easiest place to start, but they still require discipline. Traffic is synchronous, user-facing, and latency-sensitive. Small degradations show up quickly, which makes canaries effective if scoped correctly.
The key is controlled traffic weighting. Route a fixed, low percentage of requests to the new version and keep the rest on the stable path. Don’t ramp aggressively. Let the system sit long enough for cold starts, cache misses, and edge cases to surface. Avoid global rollouts and scope canaries by region, endpoint, or tenant where possible.
Event-driven canaries are harder because failure is less visible and retries distort reality. Start by limiting event exposure. Only a subset of events should flow to the new version. This keeps retry storms and cost spikes contained if something goes wrong.
Watch retry behaviour closely. Retries delay detection while amplifying load across queues, databases, and third-party systems. Also, account for delayed feedback. Event pipelines don’t fail instantly. Give canaries enough time to surface lag, backlog growth, and downstream timeouts before increasing exposure.
Also Read: How to Design Cost-Efficient CI/CD Pipelines Without Slowing Teams
Observability-first deployments treat measurement as a prerequisite. You decide what “healthy” means before you release, and you watch those signals continuously while the canary runs.
Leading indicators tell you something is wrong before users complain. In serverless, these matter more than raw error counts. Small latency shifts, rising retry rates, or increased cold starts often show up minutes before hard failures. These signals reflect system stress. If you wait for obvious errors, you’ve already missed the window where rollback is cheap.
Serverless platforms surface failure through economics and limits. Sudden cost spikes, unexpected concurrency growth, or throttling events are often the first sign of a bad canary. These aren’t finance metrics. They’re reliability indicators. When a new version behaves inefficiently or triggers retries, the bill rises before dashboards turn red. Ignoring these signals means learning about failures after they’ve scaled.
Safe canary deployments need a clear, repeatable flow that removes judgment calls during a release. When something goes wrong, the system should already know what to do. The steps below reflect how mature serverless teams operationalise canaries as part of everyday DevOps best practices.
- Define canary scope before deployment: Decide upfront how much traffic or how many events the new version is allowed to handle. This limit is non-negotiable and set before any code ships.
- Deploy the new version in isolation: Release the new function version without routing full production load to it.
- Route a controlled slice of production load: Shift a small, measurable portion of real traffic or events to the canary. Keep the rest of the system untouched.
- Continuously evaluate health signals: Monitor latency, errors, retries, cost, and concurrency in near real time. Compare against predefined baselines.
- Trigger automatic rollback on breach: If any critical threshold is crossed, revert traffic immediately.
- Expand traffic in deliberate steps: Increase exposure gradually once the canary proves stable. Each step is a checkpoint.
- Complete the rollout and clean up: Once fully deployed, remove canary-specific routing and alerts. A finished release should leave no operational residue behind.
Serverless fails when speed isn’t matched with control. Canary releases give you that control without sacrificing velocity. They turn deployments into reversible, observable steps instead of high-risk events.
When done right, canaries aren’t an extra layer of process. They’re how mature teams ship confidently in systems that scale instantly and fail loudly. They reflect strong DevOps best practices, such as clear ownership, automation over heroics, and safety built into the system. If your serverless deployments still rely on full cutovers and manual rollbacks, the risk isn’t theoretical. It’s waiting for the next release.
This is where platform thinking matters. At Linearloop, we help teams design deployment workflows where safety is encoded into the system. If you want serverless speed without production anxiety, that’s the conversation worth having.

Mayur Patel
Jan 22, 20266 min read