How to Build an Async-First Engineering Tool Stack That Scales

Mayank Patel
Mar 23, 2026
6 min read
Last updated Mar 22, 2026
Most engineering teams have a coordination problem. Work slows down because engineers are stuck in status meetings, waiting on timezone overlaps, and chasing fragmented context across Slack threads, tickets, and calls. Decisions live in conversations instead of systems. Updates require asking instead of observing. The result isn’t lack of effort. It’s execution friction caused by poor coordination design.
Async-first engineering solves this by shifting from meeting-driven workflows to system-driven execution. Instead of relying on real-time alignment, teams operate on structured context, visible work, and automated flows. This blog breaks down the most relevant developer productivity tools not as a list, but as a connected system, so work moves forward without waiting on people.
Most teams claim to be async, but still operate on sync-heavy systems. Engineers wait for responses, context gets buried in conversations, and progress depends on availability instead of systems. This creates constant interruptions, shallow work, and delayed execution.
Async-first engineering replaces this with structured, written, and system-driven workflows. Work moves forward through documented context, visible task states, and automation. Engineers operate with higher autonomy because they don’t need real-time validation to proceed. This becomes critical for remote and globally distributed teams, where deep work and uninterrupted execution directly impact delivery speed.
| Aspect | Sync-first workflow | Async-first workflow |
| Communication | Meetings, calls, instant replies | Written updates, recorded context |
| Dependency | Requires real-time availability | Independent execution |
| Visibility | Status via check-ins | Status visible in systems |
| Decision-making | Happens in conversations | Logged and documented |
| Productivity | Interrupted, reactive | Focused, deep work |
Read more: Why Teams Optimize Conversion rate Instead of Revenue
Most engineering teams lose velocity not because of complexity, but because of broken coordination layers. Work gets delayed, duplicated, or blocked due to poor visibility, scattered context, and over-reliance on meetings. These issues compound as teams scale, making execution slower despite having the right talent.
- Meeting overload: Teams rely on recurring standups, sync calls, and ad-hoc discussions to stay aligned. This interrupts deep work, increases context switching, and turns coordination into a time-heavy activity instead of a system-driven process.
- Lack of visibility: Engineers and managers constantly ask for updates because work status isn’t visible in real time. Progress tracking depends on conversations, not systems, leading to delays and unnecessary follow-ups.
- Fragmented tools: Communication, tasks, code, and documentation exist in disconnected tools. This forces manual updates, duplicate effort, and inconsistent information across systems, slowing down execution.
- Knowledge silos: Decisions and context are buried in Slack threads or meetings with no structured documentation. New team members struggle to onboard, and teams repeatedly solve the same problems due to lack of accessible knowledge.
Read more: Executive Guide to Measuring AI ROI and Payback Periods
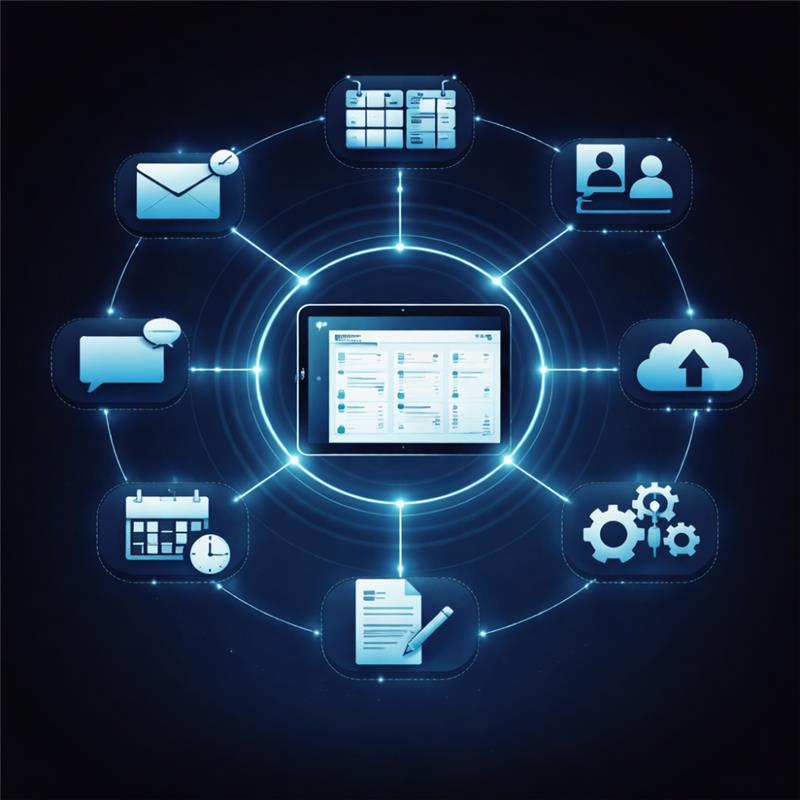
Async-first teams fix coordination by structuring tools into a connected system. Each layer solves a specific coordination gap: Communication replaces meetings, tracking replaces status checks, documentation replaces memory, and automation removes manual dependency. The goal is simple, to make work move without asking.
Layer 1: Async communication tools
Async communication tools replace real-time conversations with structured, persistent updates. Instead of meetings and instant replies, teams rely on threads, recorded videos, and written context. This ensures discussions remain searchable, decisions are traceable, and engineers can respond on their own time without blocking progress.
- Threads organise discussions instead of scattered messages
- Recorded updates replace recurring meetings
- Conversations remain searchable and reusable
- Reduces dependency on instant responses
Layer 2: Project & issue tracking tools
Project and issue tracking tools act as the execution backbone of async teams. They provide a single source of truth for tasks, bugs, and progress. Work status becomes visible without follow-ups, allowing teams to coordinate through systems instead of conversations or manual updates.
- Centralised view of tasks, bugs, and priorities
- Status tracking without meetings or check-ins
- Clear ownership and accountability
- Connects work directly to execution pipelines
Layer 3: Documentation & knowledge systems
Documentation systems replace tribal knowledge with structured, accessible information. Async teams rely on written context for decisions, architecture, and workflows. This reduces repeated discussions, improves onboarding, and ensures that knowledge persists beyond individuals or conversations.
- Stores decisions, architecture, and processes
- Eliminates repeated explanations and confusion
- Enables faster onboarding and knowledge transfer
- Acts as a long-term organisational memory
Layer 4: Code collaboration & version control
Code collaboration tools enable engineers to build and review without real-time dependency. Pull requests, comments, and version control systems create structured workflows where feedback and iterations happen asynchronously, reducing the need for live discussions while maintaining code quality.
- Pull requests enable structured async reviews
- Comments capture feedback directly in code context
- Version history ensures traceability of changes
- Reduces need for live debugging or review calls
Layer 5: Automation & CI/CD tools
Automation and CI/CD tools remove manual coordination from build, test, and deployment processes. Instead of relying on people to trigger or monitor workflows, systems handle execution automatically, ensuring consistency, speed, and reduced dependency on specific individuals.
- Automates testing, builds, and deployments
- Reduces human intervention in release cycles
- Provides real-time updates on execution status
- Ensures consistency across environments
Layer 6: AI developer tools (emerging layer)
AI developer tools reduce cognitive load by assisting with code generation, debugging, and problem-solving. In async environments, they help engineers move faster independently, without waiting for peer input, making them a critical layer in modern productivity stacks.
- Generates code and reduces repetitive work
- Assists in debugging and problem-solving
- Speeds up development cycles
- Minimises dependency on peer support
Read more: How to Deploy Private LLMs Securely in Enterprises
Most teams don’t struggle with lack of tools—they struggle with poor tool selection and disconnected stacks. Adding more tools increases complexity. The goal is not to adopt popular tools, but to design a stack where every layer reduces coordination cost and integrates seamlessly into execution workflows.
- Avoid tool overload: More tools create more context switching and fragmentation. Limit your stack to essential layers and ensure each tool has a clear role. Redundancy across tools leads to confusion, duplicate updates, and slower execution.
- Map tools to workflows: Start with how your team works, from idea to deployment. Choose tools that fit your execution flow instead of forcing workflows to adapt to tool limitations.
- Prioritise integration over capability: A tool that integrates well is more valuable than a feature-rich isolated tool. Ensure seamless flow between communication, tasks, code, and CI/CD to eliminate manual updates.
- Optimise for visibility without asking: Every tool should contribute to making work status observable. If progress still requires follow-ups or meetings, the stack is not solving the core problem.
- Choose based on team maturity: Early-stage teams need speed and simplicity, while larger teams may require structured workflows and governance. Avoid over-engineering in small teams and under-structuring in scaled environments.
- Reduce dependency on real-time coordination: Select tools that support asynchronous updates, documentation, and automation. If a tool requires constant real-time interaction to function, it will break async workflows.
- Standardise, don’t personalise excessively: Too many custom workflows or configurations create inconsistency. Standardise how tools are used across teams to ensure clarity, scalability, and easier onboarding.
Read more: How Brands Use Digitized Loyalty Programs to Control Secondary Sales
Most teams adopt async tools but continue operating with sync-first habits. This creates a mismatch where tools exist, but coordination problems persist. The issue is how teams use them. These mistakes reintroduce dependency, reduce visibility, and break the async execution model.
- Over-reliance on chat tools (Slack-first culture): Teams treat chat as the primary system of record. Important decisions get buried in threads, making information hard to retrieve and forcing repeated discussions instead of structured documentation.
- Replacing meetings with unstructured communication: Async requires structured updates. Without clear formats for communication, teams create ambiguity, leading to misalignment and delayed execution.
- Lack of documentation discipline: Teams skip documenting decisions, architecture, and workflows. This leads to knowledge gaps, repeated problem-solving, and slower onboarding for new team members.
- Poor tool integration: Disconnected tools force manual updates across systems. Tasks, code, and deployments don’t sync, creating inconsistencies and increasing coordination overhead.
- No clear ownership or accountability: Async systems fail when ownership is unclear. Without defined responsibility, tasks remain idle, and progress depends on follow-ups instead of system-driven execution.
- Over-engineering the stack early: Early-stage teams adopt complex tools designed for large organisations. This slows execution, increases setup overhead, and creates unnecessary process friction.
- Ignoring onboarding and workflows: Async systems require clear onboarding and documented workflows. Without this, new team members struggle to understand processes, reducing overall team efficiency.
Read more: Why SKU-Based Catalogs Fail for Base + Tint Business Model
Async-first engineering is not about reducing meetings or switching tools—it is about redesigning how work moves through your system. When communication is structured, work is visible, decisions are documented, and execution is automated, teams stop depending on availability and start operating with consistency and speed across time zones.
The real shift is system design, not effort. If your current stack still relies on follow-ups, meetings, and fragmented context, it is creating friction by default. At Linearloop, we help engineering teams design async-first systems that reduce coordination overhead and improve execution velocity across workflows, tooling, and infrastructure.
Related Posts
How to Use CodeRabbit and Mutable.ai for Faster PR Reviews
PR reviews and documentation are slow because they are repetitive. The same comments show up in every PR. The same gaps appear in documentation. Engineers spend hours checking naming, structure, and obvious issues instead of focusing on what actually matters, such as system behaviour, edge cases, and long-term impact. Over time, this creates review fatigue, inconsistent documentation, and slower merge cycles.
This is not a tooling problem. It is a workflow problem. Most teams still rely on humans to do predictable work that machines can handle. That is where automation changes the game. This blog breaks down how to shift repetitive PR checks and documentation work to tools like CodeRabbit and Mutable.ai, so your engineers can focus on thinking, not repeating.
Read more: How Limearloop Built a Zero-Loss ERP for a Gold Refinery: Gold VGR ERP Case Study
PR reviews are not breaking because engineers lack skill. They are breaking because the process forces them to do the same work repeatedly. Most reviews fail on repetition, context switching, and fatigue. The result is slower merges, inconsistent quality, and senior engineers spending time where it doesn’t matter.
- Reviewers keep checking the same basics: Every PR triggers the same checklist including naming conventions, formatting issues, missing tests, small refactors. These are necessary, but predictable. When humans handle this repeatedly, reviews become mechanical instead of thoughtful.
- Constant context switching kills depth: Reviewers jump between files, comments, diffs, and tools. This fragmentation breaks focus. Instead of analysing system impact, they spend time navigating the codebase and piecing context together.
- Review fatigue reduces review quality: As PR volume increases, attention drops. Reviews become shallow. Important issues slip through because energy is spent on obvious fixes rather than deeper analysis.
- Senior engineers are doing low-leverage work: Highly experienced engineers end up pointing out indentation issues and missing comments. Their time shifts from architecture and decision-making to basic validation tasks.
- Merge cycles slow down unnecessarily: Back-and-forth comments on predictable issues delay approvals. Fixes that could be automated create multiple review cycles, stretching timelines without adding real value.
Read more: Personalization vs Broad UX Changes in Conversion Rate Optimization Services
Documentation is incomplete because it is always treated as something that can be done later. Code gets written, reviewed, and shipped under pressure, while documentation is pushed to the side as a non-urgent task. When it is finally written, it is rushed, inconsistent, and often disconnected from the actual implementation. Since it relies entirely on manual effort, every engineer writes differently, follows a different structure, and prioritises it differently, which leads to fragmented and uneven documentation across the codebase.
Most of the real understanding stays in engineers’ heads instead of being captured in the system. New developers don’t rely on documentation because they know it’s outdated. Instead, they rely on people. This slows down onboarding and increases dependency on specific individuals. As the code evolves, documentation rarely keeps up, creating a growing gap between what is written and what actually exists. Over time, documentation stops being useful and starts being ignored.
Read more: Personalization vs Broad UX Changes in Conversion Rate Optimization Services
Boring work in engineering refers to tasks that are repeatable, predictable, and required every single time, regardless of the complexity of the feature. Writing docstrings, adding validations, pointing out naming issues, or leaving basic review comments, these are all necessary to maintain code quality, but they do not require deep thinking or context-heavy decision-making.
The problem is not the work itself, but how often it repeats and how it scales. As the team grows and PR volume increases, these tasks multiply quickly and start consuming a significant portion of engineering time. They don’t demand expertise, but they demand attention, and that attention comes at the cost of higher-value thinking. Over time, engineers spend less time solving problems and more time repeating patterns.
Read more: How to Optimize Demo Request Flows Without Disrupting Sales Infrastructure
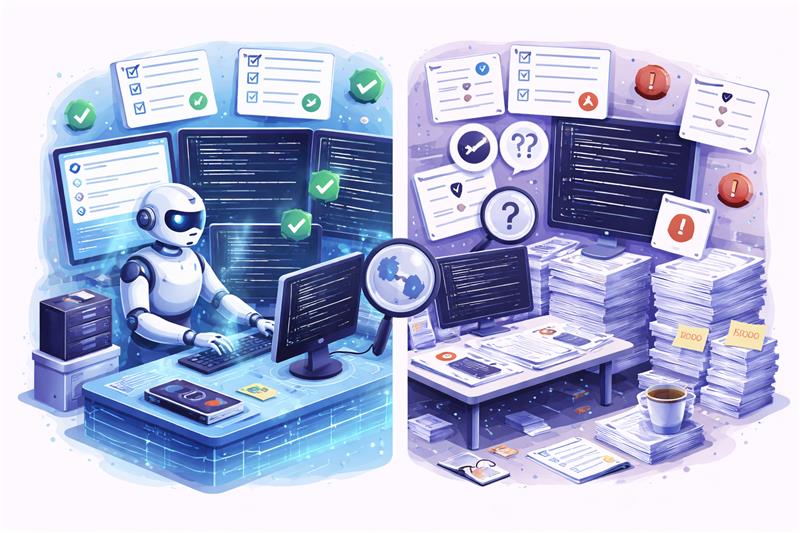
The problem is that the teams are using human effort in the wrong places. Repetitive work does not need intelligence, it needs consistency. That is where machines fit naturally. When you shift repeatable checks and documentation tasks to automation, you free engineers to focus on what actually requires judgment. This is about removing the parts of the workflow that never needed them in the first place.
- CodeRabbit → Handles PR automation
- Runs first-pass reviews instantly
- Flags basic issues, missing tests, and anti-patterns
- Reduces repetitive feedback before human review
- Mutable.ai → Handles documentation automation
- Generates docstrings and code explanations
- Keeps documentation aligned with implementation
- Reduces manual effort and inconsistency
Read more: From Custom Builds to 60 Stores: BVB Media E-Commerce Platform Story
PR reviews slow down because humans are doing the first pass manually, and that first pass is almost always predictable. Most issues flagged in early reviews are repetitive, obvious, and consistent across PRs. This is where CodeRabbit changes the workflow by handling the mechanical layer before a human even looks at the code.
- Automated first-pass reviews remove the obvious work: Instead of waiting for a reviewer to go through the PR line by line, CodeRabbit runs an immediate review as soon as the PR is raised. It catches the kind of issues that reviewers repeatedly point out, allowing the author to address them upfront.
- Detects anti-patterns, missing tests, and style inconsistencies: It identifies common anti-patterns, flags missing or weak test coverage, and highlights deviations from coding standards. These are important checks, but they do not require human judgment every single time.
- Provides inline suggestions that are easy to act on: Feedback is not abstract. It is placed directly within the PR, with clear suggestions that developers can fix without additional back-and-forth, reducing unnecessary review cycles.
- Reduces reviewer workload before human involvement: By the time a human reviewer steps in, the PR is already cleaner. Basic issues are resolved, and the reviewer can focus on deeper concerns like logic, architecture, and edge cases.
- Improves overall PR quality before the review even begins: The baseline quality of every PR increases. Fewer iterations. Fewer comments. More meaningful reviews. The process becomes faster, but more importantly, it becomes more focused.
Read more: Why Some Lead Form Fields Kill Conversion
Documentation breaks because it depends entirely on manual effort, and manual effort is always deprioritised when shipping pressure increases. Engineers focus on writing code that works, not documenting it consistently. This is where Mutable.ai changes the workflow by making documentation a byproduct of writing code, not a separate task that gets delayed or skipped.
- Auto-generates docstrings and explanations as code is written: Instead of expecting engineers to go back and document everything manually, Mutable.ai generates clear docstrings and function-level explanations alongside the code, ensuring that documentation exists from the start rather than being added later.
- Keeps documentation aligned with the actual implementation: Since documentation is generated based on the code itself, it evolves as the code changes. This reduces the common problem where documentation becomes outdated and no longer reflects the current logic.
- Explains logic in a way that supports onboarding: New developers do not need to rely entirely on teammates to understand the codebase. Generated explanations provide immediate context, making it easier to understand what the code is doing and why.
- Reduces dependency on manual writing and individual habits: Different engineers have different documentation styles and priorities. Automation removes this inconsistency by creating a standardised layer of documentation across the codebase.
- Creates a default documentation layer that always exists: Even if no one explicitly writes detailed documentation, there is always a baseline available. This ensures that documentation is never missing, even if it is later refined or expanded.
Read more: Why Teams Optimize Conversion Rate Instead of Revenue
The difference is structural. Most teams are still operating in a workflow where humans handle everything, from basic checks to deep reviews, and documentation sits outside the development flow. Once you shift repetitive work to automation, the entire system becomes faster, cleaner, and more focused.
| Before (manual workflow) | After (automated workflow) |
| Reviews begin with humans checking everything manually, including basic and predictable issues that repeat across every PR. | Reviews begin with automated pre-review, where tools handle the first pass and surface issues before a human gets involved. |
| Feedback loops are repetitive, with the same comments appearing across multiple cycles, slowing down approvals and frustrating both authors and reviewers. | PRs are cleaner from the start, as common issues are already addressed, reducing back-and-forth and accelerating the review process. |
| Documentation is written separately, often delayed or skipped, and rarely stays aligned with the actual implementation over time. | Documentation is generated alongside code, ensuring that it exists by default and stays closer to the current logic. |
| Reviewers spend time on validation and formatting instead of analysing deeper system behaviour and long-term impact. | Humans focus on architecture, edge cases, and decision-making, where their expertise actually creates value. |
Read more: How BeatRoute Connects Brands, Distributors, and Retailers in One System
This is where the shift becomes real. Not in theory, but in how your day-to-day engineering workflow actually changes. The goal is simple—remove repetitive friction before it reaches humans, so reviews become faster, cleaner, and more meaningful.
The workflow still starts the same, but the expectation changes. Code is written with the understanding that the first layer of validation will be automated.
- Focus stays on logic, not formatting
- Less mental load on remembering standards
- Code is prepared for automated checks
As soon as the PR is raised, CodeRabbit performs a first-pass review, catching predictable issues without waiting for human input.
- Flags naming, structure, and style issues
- Identifies missing tests and common anti-patterns
- Surfaces feedback instantly within the PR
Instead of waiting for reviewer comments, developers resolve flagged issues upfront, reducing unnecessary review cycles.
- Faster iteration before human review
- Fewer back-and-forth comments
- Cleaner PR before it is seen by others
Documentation is no longer delayed or skipped. It is created alongside the code, making it part of the development flow.
- Docstrings and explanations are auto-generated
- Logic is captured in real time
- Documentation exists by default, not by effort
By the time a reviewer steps in, the PR is already refined, allowing attention to shift to what actually matters.
- Focus on architecture and system behaviour
- Evaluate edge cases and trade-offs
- Review decisions
With fewer iterations and clearer reviews, approvals happen quicker without compromising quality.
- Reduced cycle time across PRs
- Higher baseline code quality
- More confidence in what gets merged
Read more: How to Build an Async-First Engineering Tool Stack That Scales
Automation removes repetition. It handles predictable checks, but it cannot understand intent, context, or long-term consequences the way engineers do. That layer still belongs to humans, and it is where real engineering value shows up.
- Architecture decisions: Architecture decisions require understanding how different parts of the system interact over time, not just whether the code works today. Choosing patterns, defining boundaries, and ensuring scalability involves context that automation cannot fully grasp, especially when trade-offs affect performance, maintainability, and long-term product evolution.
- Trade-offs and edge cases: Every non-trivial system involves trade-offs between performance, simplicity, cost, and reliability. Edge cases often emerge from real-world usage. Identifying and prioritising these requires experience and judgment, because not every edge case should be solved the same way or at the same level.
- Business logic validation: Code can be syntactically correct and still be functionally wrong. Validating whether the implementation aligns with business requirements, user expectations, and product goals requires domain understanding. This is where engineers connect technical execution with real-world outcomes, something automation cannot reliably interpret on its own.
- Risk and system impact: Changes in one part of the system can have unintended consequences elsewhere. Understanding dependencies, failure scenarios, and potential risks requires a broader system view. Engineers assess how changes behave under load, during failures, or across integrations, which goes beyond what automated checks can safely evaluate.
- Code ownership and accountability: Automation can suggest, but it cannot take responsibility. Engineers own the code they write and review, including its behaviour in production. Accountability involves making decisions, standing by them, and continuously improving the system, which requires human ownership that cannot be delegated to tools.
Read more: How to Build an Async-First Engineering Tool Stack That Scales
When repetitive work is removed, the impact is immediate and structural. Reviews get sharper, documentation becomes usable, and engineering time shifts back to actual problem-solving instead of routine validation.
- Faster PR cycles: PR cycles shorten because basic issues are resolved before human review. Fewer iterations, fewer comments, and quicker approvals. Teams spend less time waiting and more time moving work forward without unnecessary delays or repeated review loops.
- Reduced review fatigue: Reviewers stop wasting energy on repetitive checks. Their focus shifts to logic, architecture, and system behaviour. This reduces mental fatigue and improves consistency, because attention is no longer diluted across low-value validation tasks.
- Better consistency across codebase: Automation applies the same standards across every PR without variation. This removes inconsistency caused by individual preferences or oversight. The codebase becomes more predictable, easier to navigate, and simpler to maintain as it grows.
- Improved onboarding speed: New engineers understand the codebase faster because documentation is always present and aligned. They rely less on people and more on the system. This reduces dependency and shortens the time it takes to become productive.
- Stronger knowledge sharing: Knowledge moves from individuals into the system. Documentation stays updated and accessible, reducing gaps and making collaboration easier across teams, even as the codebase and team size increase.
- More time for deep work: Engineers spend less time on predictable tasks and more time on complex problem-solving. Time shifts from repetition to thinking, which improves both productivity and the quality of engineering decisions.
Read more: Multi-File Refactoring with AI: Cursor vs Windsurf vs Copilot
PR reviews and documentation do not need more effort. They need a better workflow. Most teams are still using engineers for predictable work that machines can handle, which slows everything down and reduces the quality of what actually matters. When you remove repetition from the system, reviews become focused, documentation becomes reliable, and engineering time shifts back to decision-making and problem-solving.
This is exactly where Linearloop fits. Not as a tool layer, but as a workflow rethink. We help teams redesign how reviews, documentation, and engineering processes actually work—so automation handles the predictable, and your engineers focus on what moves the system forward.

Mayank Patel
Apr 6, 20265 min read
Why Developers Lose Productivity After Weekends (And How To Fix It)
The modern engineering workflow carries an overlooked inefficiency that becomes most visible after a break. Developers return to the same codebase, the same tasks, and the same systems, yet struggle to resume meaningful progress. The gap is not in execution, but in cognition. What is lost is not code, but context.
This reveals a fundamental issue in how productivity is currently approached. Most systems optimise for speed of output, while neglecting continuity of understanding. As a result, developers spend a significant portion of time reconstructing decisions, dependencies, and intent before they can proceed. Productivity, therefore, is not constrained by how fast work is done, but by how quickly thinking can be resumed.
Also Read: How Univia Built a Scalable AgriTech System
What disappears after a break is not code, but context. The system remains intact, yet the reasoning behind it fades. Developers lose track of active decisions, underlying assumptions, and how different parts of the system connect. What was once a clear mental model becomes fragmented. Resuming work, therefore, begins with reconstruction.
→ Active decisions lose clarity
→ Assumptions become invisible
→ System relationships break
→ In-progress thinking resets
This is a cognitive gap. Most systems store code and track tasks, but they do not preserve intent. As a result, developers must rebuild understanding before they can proceed.
Context rebuilding replaces forward progress. This reconstruction is expensive. Developers spend hours scanning code, pull requests, and tickets just to reorient themselves. The cost compounds quickly, resulting in delays increasing, errors becoming more likely, and the same decisions being revisited. Execution slows down, because continuity is missing.
Also Read: Multi-File Refactoring with AI: Cursor vs Windsurf vs Copilot
The limitation is what the tools are designed to optimise. Most productivity systems are built around execution, containing writing, deploying, and tracking, while continuity of understanding remains unaddressed. As a result, they support doing work, but not resuming it.
- Tools optimise for execution: IDEs, task managers, and CI pipelines are structured around action. They help developers write code, track tasks, and ship changes. However, they do not retain the reasoning behind those actions. Intent, assumptions, and intermediate thinking are not captured, making it difficult to reconstruct context after a break.
- Documentation fails in real workflows: Documentation is expected to bridge this gap, but it rarely reflects the current state of the system. It is often outdated, overly generic, or disconnected from actual implementation decisions. As a result, developers do not rely on it when resuming work, and instead return to the codebase to rebuild understanding manually.
Resuming work after a break should not require reconstruction. A well-designed workflow allows developers to re-enter the system with clarity. The current state of work, the intent behind recent changes, and the next logical step should be immediately visible. The experience should feel continuous, as if no interruption occurred, rather than requiring effort to rebuild understanding.
This continuity is reflected through clear signals. The last working checkpoint is identifiable, recent decisions are traceable, and system relationships remain visible. Minimal re-reading is required, and dependencies do not need to be rediscovered. When context is preserved, developers do not spend time figuring out where they are. They proceed directly with what needs to be done.
Also Read: How to Optimise Demo Request Flows Without Disrupting Sales Infrastructure
Context loss is not addressed by a single tool, but by how systems preserve and reconstruct understanding across workflows. The objective is to reduce the effort required to resume thinking. This requires tools that capture intent, surface relationships, and make recent changes interpretable without manual reconstruction.
- Context capture tools: These tools preserve the state of work at a specific point in time. They capture checkpoints, notes, and intermediate decisions, allowing developers to return to a clear snapshot of what was in progress and what remained unresolved.
- Code understanding tools: These tools help reconstruct system understanding directly from the codebase. They summarise structure, dependencies, and behaviour, reducing the need for deep manual inspection when reorienting after a break.
- Change intelligence tools: These tools make recent changes interpretable. They summarise commits and pull requests, enabling developers to understand what changed and why without scanning history in detail.
- Workflow memory systems: These systems capture decision context alongside tasks. They document why choices were made and how work connects, creating a persistent record of reasoning that supports resumption.
- System visualisation tools: These tools externalise architecture and dependencies. By representing system relationships visually, they reduce the cognitive effort required to rebuild mental models.
Also Read: Modern AI Data Stack Architecture Explained for Enterprises
The difference between ineffective and effective workflows becomes visible after a break. In most cases, developers do not resume work; they reconstruct it. Time is spent scanning code, revisiting pull requests, and reconnecting context before progress begins. This is a continuity gap.
A context-aware workflow removes this friction. It makes the state of work, recent changes, and intent immediately accessible. Reorientation is reduced, and execution follows without delay.
- Before: Typical Monday restart
Work begins with uncertainty. Developers scan code, review pull requests, and revisit tasks to understand where they left off. Context is fragmented, and time is spent reconstructing intent before any progress is made.
- After: Context-aware workflow
Work begins with clarity. The last checkpoint is visible, changes are summarised, and intent is accessible. Developers resume directly, without rebuilding context.
The difference is not in tooling volume, but in how workflows are designed. High-performing teams do not optimise only for execution speed. They structure systems to preserve context, reduce rethinking, and maintain continuity across interruptions. As a result, resuming work becomes predictable.
- They design for continuity: These teams prioritise how work is resumed, not just how it is executed. Systems are structured to make the current state, recent changes, and next steps immediately visible. The focus is on reducing reorientation time rather than increasing output velocity.
- They capture decisions: Instead of only tracking tasks and code changes, they document the reasoning behind them. Decisions, trade-offs, and assumptions are recorded as part of the workflow. This creates a reliable reference point when work is resumed, eliminating the need to infer intent.
- They reduce cognitive load structurally: Cognitive load is addressed at the system level. Dependencies are visible, workflows are predictable, and context is not scattered across tools. This reduces the need for repeated interpretation and allows developers to focus on execution without rebuilding understanding.
Tool selection often focuses on features and integrations, but the more relevant criterion is how effectively a tool preserves and restores context. The goal is to reduce the effort required to resume meaningful work. Tools should be evaluated based on their ability to retain intent, surface relationships, and make recent changes interpretable without manual reconstruction.
- Evaluate based on context preservation: Assess whether the tool helps answer three questions immediately: Where work stopped, why it was structured that way, and what should happen next. Tools that require additional interpretation or cross-referencing increase cognitive load rather than reduce it.
- What to prioritise vs ignore:
| Prioritise | Ignore |
| Tools that capture intent alongside actions | Tools focused only on speed of execution |
| Systems that make recent changes interpretable | Tools that require ma |
| Workflows that expose dependencies clearly | Tools that fragment context across multiple layers |
| Platforms that retain decision history | Tools that only track tasks without reasoning |
The loss of productivity after a break is not caused by lack of effort, but by loss of context. When workflows fail to preserve intent, developers are forced to reconstruct understanding before they can proceed. This shifts time away from execution towards reorientation, making continuity the primary constraint on productivity.
Addressing this requires a shift in how systems are designed. Instead of optimising only for speed, workflows must be structured to retain and surface context consistently. This is where Linearloop focuses on, building engineering systems that reduce cognitive overhead and enable teams to resume work with clarity.
Mayank Patel
Apr 3, 20265 min read